Research
My research focuses on video generation and editing and post-training for image/video models. I am particularly interested in modeling physical dynamics and object interactions to generate realistic, controllable videos. My previous work explored diffusion distillation and efficient one-step generation for applications such as video enhancement and image inpainting. Across these areas, I aim to improve generation quality and controllability while reducing computational cost, making generative AI more scalable, efficient, and accessible.
Selected Publications
* denotes equal contribution
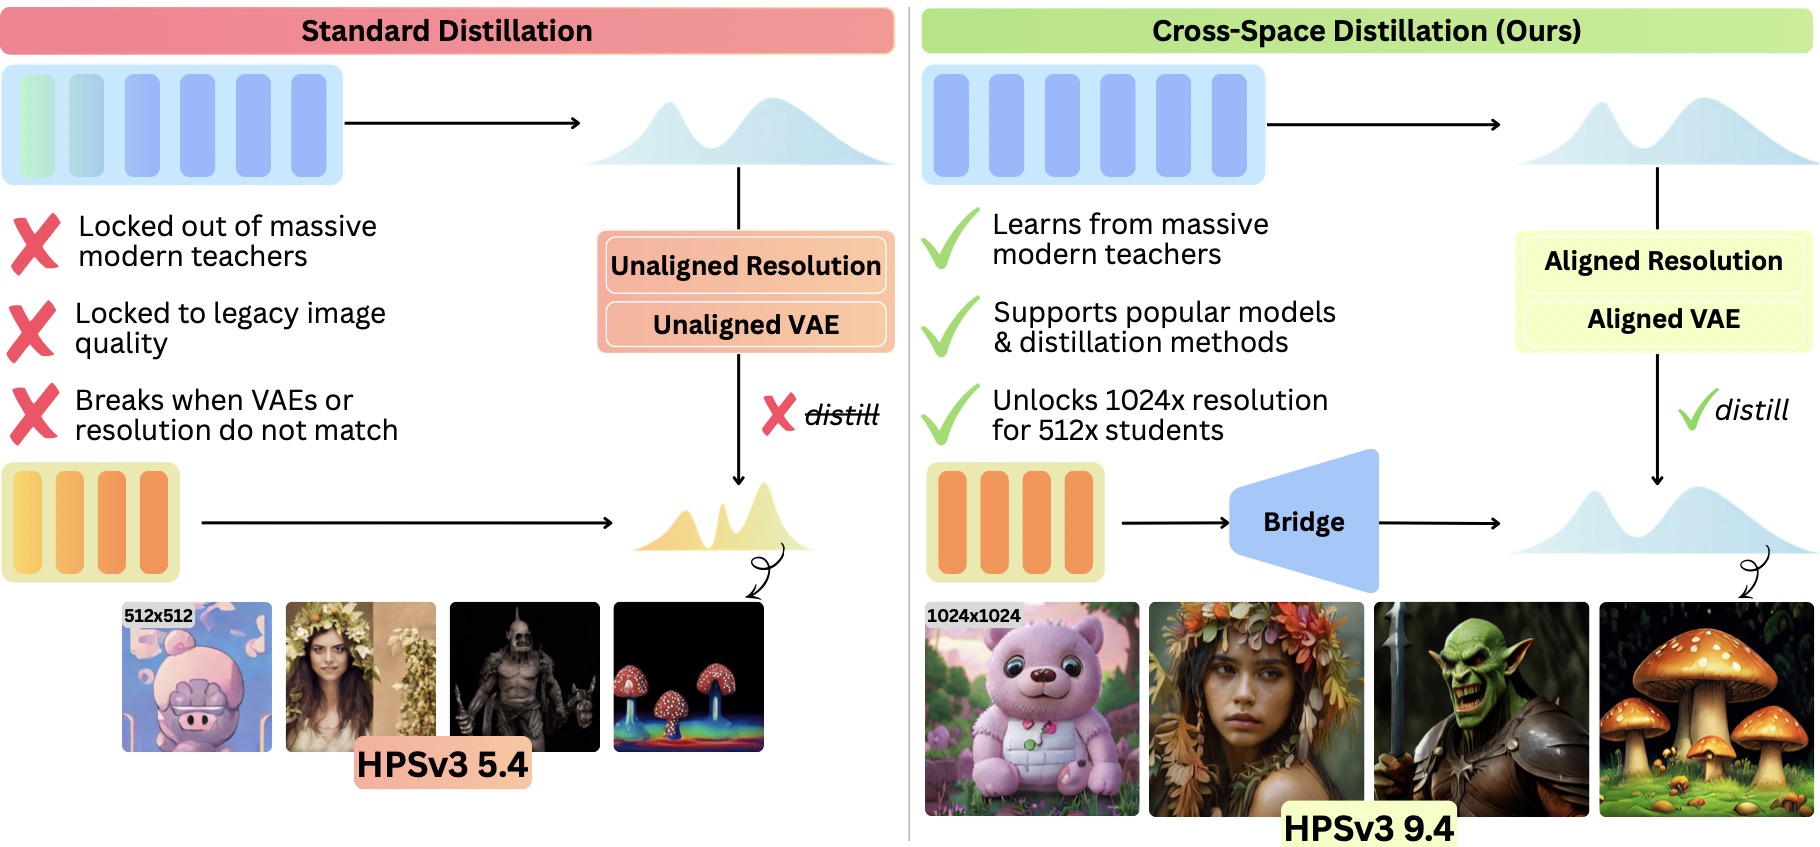
We formalize Cross-Space Distillation and introduce Bridge, a lightweight latent-space interface that makes standard one-step distillation possible across mismatched resolutions, VAEs, architectures, and diffusion/flow paradigms.
A memory-efficient adversarial attack against diverse image-to-video diffusion models, enabled by robust dual-space perturbation optimization.
A highly efficient one-step inversion diffusion network for high-quality few-step image inpainting.
iSM resolves five major shortcut-model flaws with dynamic guidance, wavelet loss, sOT, and Twin EMA, yielding markedly better image generation.
An improved SwiftBrush version that makes the one-step diffusion student beats its multi-step teacher.
A high-quality dataset centered on extreme pose faces, supporting face synthesis, reenactment, recognition benchmarking, and more.